Reference docs for everything below: commandcode.ai/docs/taste.
Jev put "not an LLM" on the map. taste-1 has been in that category since it shipped. It is a meta neuro-symbolic decision model for one domain, coding taste, running at 100T-token scale this year.
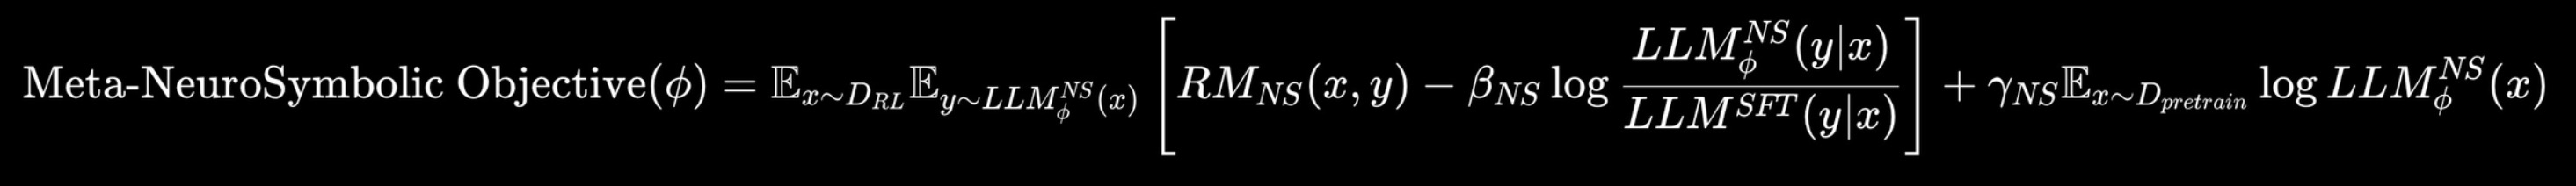
Is it an LLM? No. Then why does taste make LLM calls? Because a model that does not produce text needs one that does, on both sides of it.
Diagrams first, prose second. The talk version:
1. Two kinds of model
┌────────────────────────────────────────────────────────────────────────┐│ TWO KINDS OF MODEL │├────────────────────────────────────────────────────────────────────────┤│ LLM DECISION MODEL ││ ────────────────────────── ────────────────────────── ││ in text text, or structured state ││ out text, one token at a time typed decision + probability ││ loop sample → append → sample … none. one forward pass ││ can chat, write code, explain classify, score, rank, route ││ can't promise a type, or a number write a sentence ││ that means anything ││ fails by hallucinating being wrong, and saying how ││ sure it was │└────────────────────────────────────────────────────────────────────────┘
The right column gives up text generation on purpose. It cannot write a paragraph, so it cannot hallucinate one. It does a fixed amount of work per input, so it is cheap and fast to serve.
TypeSafe AI's Jev is the clearest public example. Their FAQ answers "Is Jev just a smaller LLM?" with a no. Their docs say a System One model "returns typed decisions and probabilities rather than generated text". Words for people on the left. Decisions for software on the right.
taste-1 lives in the right column. So does Jev.
2. What taste-1 does
┌────────────────────────────────────────────────────────────────────────┐│ SIGNAL IN, LEARNING OUT │├────────────────────────────────────────────────────────────────────────┤│ { kind: "edit", { preference: true, ││ before: "…", ┌─────────┐ category: "typescript", ││ after: "…", ───▶ │ taste-1 │ ───▶ confidence: 0.83 } ││ context: "…" } └─────────┘ ││ or ││ accept · reject · { preference: false } ││ edit · correction diff ││ ││ no prose in. no prose out. │└────────────────────────────────────────────────────────────────────────┘
Give it a signal. It decides three things. Real preference or noise? Which category? How confident? No prose in, no prose out.
Its output has the shape of a classifier. It decides, it does not write. What produces that decision is not a simple classifier. It is a meta neuro-symbolic architecture, and that architecture does things a large language model cannot.
3. The architecture
taste-1 has a strong neuro-symbolic architecture. Two halves check each other, and a loop on top learns how to weigh them.
╔════════════════════════════════════════════════════════════════════════╗║ META NEURO-SYMBOLIC ARCHITECTURE ║╠════════════════════════════════════════════════════════════════════════╣║ ┌──────────────────────────────────────────┐ ║║ │ META LOOP │ ║║ │ re-scores old learnings on new evidence │ ║║ │ confidence ↑ when a preference repeats │ ║║ │ confidence ↓ when you contradict it │ ║║ │ reorganizes categories as profile grows │ ║║ └──────────┬───────────────────▲───────────┘ ║║ weights │ │ feedback ║║ ▼ │ ║║ signal ▶ ┌────────────────────┐ ┌────────────────────┐ ▶ learning ║║ │ NEURAL │◀─▶│ SYMBOLIC │ + confidence ║║ │ learned intuition │ │ rule layer │ ║║ │ "this looks like a │ │ fixed categories │ ║║ │ preference for X" │ │ confidence scoring │ ║║ │ patterns you would │ │ relations between │ ║║ │ never write down │ │ learnings │ ║║ │ │ │ contradiction check│ ║║ └────────────────────┘ └────────────────────┘ ║║ intuition consistency ║║ ║║ neural proposes. symbolic constrains. a proposal that breaks the ║║ profile's structure is flagged, not applied. ║╚════════════════════════════════════════════════════════════════════════╝
Neural. The learned half of the architecture reads the signals an LLM has extracted and forms an intuition about what you prefer. This is the half that picks up the patterns you would never write down, like where you split a function, which abstractions you reach for, and what you reject on sight.
Symbolic. A rule layer holds the structure of a taste profile. It knows the categories a learning can belong to, how to score confidence, how learnings relate to each other, and what counts as a contradiction. When a new preference conflicts with an established one, this layer flags the conflict instead of letting the new one overwrite the old.
Meta. The continuous learning loop. Every accept, reject and edit is feedback on earlier decisions, so taste-1 re-scores old learnings as well as classifying new ones. Confidence rises when a preference keeps showing up and falls when you contradict it. As the profile grows, the loop reorganizes learnings into categories.
Neural for intuition. Symbolic for consistency. Meta for correction over time. None of the three generates text.
Here is the meta loop on one learning over nine days.
┌────────────────────────────────────────────────────────────────────────┐│ ONE LEARNING, NINE DAYS │├────────────────────────────────────────────────────────────────────────┤│ "prefers named exports over default exports" category: typescript ││ ││ 1.0 ┤ ││ 0.9 ┤ ●───● enforced ││ 0.8 ┤ ●───●───● ││ 0.7 ┤ ●───● ││ 0.6 ┤ ●───● hint ││ 0.5 ┤ ● ││ 0.4 ┤ ✕ contradiction ││ 0.3 ┤ (you accepted a ││ └───┬────┬────┬────┬────┬────┬────┬────┬────┬─ default export) ││ d1 d2 d3 d4 d5 d6 d7 d8 d9 ││ ││ ● signal agreed with the learning ✕ signal contradicted it ││ the ✕ on d6 pulled confidence down. three more ● pushed it back up. ││ below ~0.6 a learning stays a hint. above it, taste enforces it. │└────────────────────────────────────────────────────────────────────────┘
Do the same job with an LLM and it costs about 100x more, runs about 8x slower, and hallucinates preferences. That is why the neuro-symbolic architecture wins here.
4. Why not let an LLM decide?
Many tools ask an LLM to read your diffs and write down your preferences. An LLM is trained to produce text a person will like, not a decision software can act on.
Here is what "run it twice" looks like for each.
┌────────────────────────────────────────────────────────────────────────┐│ SAME INPUT, RUN TWICE │├────────────────────────────────────────────────────────────────────────┤│ LLM taste-1 ││ ────────────────────────── ────────────────────────── ││ run 1 "prefers named exports, { typescript, 0.83 } ││ confidence 0.9" ││ run 2 "likes explicit exports, { typescript, 0.83 } ││ confidence 0.7, also ││ seems to prefer barrel ││ files" ││ ││ different wording, same input, same decision. ││ different number, one it evaluates. it does not ││ invented preference. sample. ││ nothing trained the ││ number to mean anything. │└────────────────────────────────────────────────────────────────────────┘
Four things go wrong with the LLM route.
It fills gaps. Ask "what does this developer prefer?" and it answers whether or not the diffs support an answer. Where the evidence is thin it reaches for what developers usually prefer. In a taste profile that is a bug, because a made-up preference gets enforced on every later turn.
It does not hold still. Ask the same LLM twice and you get two different profiles. TypeSafe ran a 14-question rubric over one insurance claim 15 times and found the LLM answers moved from run to run, at temperature 0 too, with the models disagreeing with themselves on the judgment calls. Taste is nothing but judgment calls. A profile that changes on every run is not your profile.
Its confidence is a number it wrote. Ask an LLM for a confidence score and it gives you one, in the style of a probability. Nothing trained it to make that number match how often it is right. Models trained with human feedback are overconfident by construction, because raters reward sounding sure.
It starts over. An LLM has no memory of its earlier decisions. Each pass starts blank, so it re-learns what it already recorded and cannot tell a new contradiction from an old one.
| An LLM judging taste | taste-1 |
|---|---|
| Invents a preference when the evidence is thin | Returns low confidence or no learning. Its answers are drawn from a fixed set, so it cannot write a preference that is not in the input |
| Different answer on every run | Same input, same decision. It evaluates, it does not sample |
| Confidence is a number it wrote | Confidence is a calibrated score. Higher confidence means the learning is right more often, and the meta loop adjusts it against later evidence |
| Can invent new categories on the fly | The symbolic layer fixes the set of categories it can pick from |
| Starts fresh each pass | Carries prior decisions forward and re-scores them |
Can taste-1 still be wrong? Yes. The difference is that its confidence is calibrated. Taste enforces a high-confidence learning, keeps a low-confidence one as a hint, and flags a conflicting signal instead of applying it. None of that works when the confidence number was made up.
5. Why taste still needs LLMs
A model that cannot produce text needs a model that can, on both sides of it. Four steps. LLMs at two of them.
╔════════════════════════════════════════════════════════════════════════╗║ THE PIPELINE. FOUR STEPS, LLMs AT TWO OF THEM ║╠════════════════════════════════════════════════════════════════════════╣║ ┌──────────────────────────────────────────┐ ║║ │ you, coding in Command Code │ ║║ │ prompts · accepts · rejects · edits │ ║║ │ correction diffs from your commits │ ║║ └────────────────────┬─────────────────────┘ ║║ │ raw, unstructured ║║ ▼ ║║ ┌─────────────────────────────────────────────────────────────┐ ║║ │ 1. INPUT · LLM (yours to pick) │ ║║ │ reads the text and diffs │ ║║ │ turns them into structured signals │ ║║ └────────────────────┬────────────────────────────────────────┘ ║║ │ structured signals ║║ ▼ ║║ ╔═════════════════════════════════════════════════════════════╗ ║║ ║ 2. LEARN · taste-1 (meta neuro-symbolic, not an LLM) ║ ║║ ║ classifies the symbolic space of each signal: ║ ║║ ║ real preference or noise? ║ ║║ ║ which category? (cli · typescript · architecture …) ║ ║║ ║ how confident? (0 → 1) ║ ║║ ║ generates no text ║ ║║ ╚════════════════════╤════════════════════════════════════════╝ ║║ │ typed learnings + confidence ║║ ▼ ║║ ┌─────────────────────────────────────────────────────────────┐ ║║ │ 3. OUTPUT · LLM (yours to pick) │ ║║ │ writes the learnings as readable markdown │ ║║ │ merges them with what is already known │ ║║ └────────────────────┬────────────────────────────────────────┘ ║║ │ markdown ║║ ▼ ║║ ┌──────────────────────────────────────────┐ ║║ │ 4. STORE · the CLI │ ║║ │ .commandcode/taste/**/taste.md │ ║║ │ read back into every later turn │ ║║ └──────────────────────────────────────────┘ ║║ ║║ LLM steps swap them in /config, Feature models ║║ taste-1 the decision step. not a text model, not swappable ║╚════════════════════════════════════════════════════════════════════════╝
The LLMs handle the words. Neither decides what you prefer.
The LLM steps are yours to configure
Steps 1 and 3 are ordinary text work, so you get to pick which model does them.
┌────────────────────────────────────────────────────────────────────────┐│ /config → FEATURE MODELS │├────────────────────────────────────────────────────────────────────────┤│ row controls config key ││ ─────────────── ───────────────────────────── ──────────────────── ││ Taste learning the LLM around taste-1 in a featureModels ││ session. defaults to the .tasteLearning ││ model you are coding with ││ /learn-taste the LLM used to bootstrap featureModels ││ taste from existing repos or .tasteOnboarding ││ sessions in other agents ││ ││ BYOK provider? the LLM steps run on it too. │└────────────────────────────────────────────────────────────────────────┘
Inspect the traffic and you will see LLM calls on the model you picked. Those are steps 1 and 3. The Usage page in Studio lists them under the taste-1 label. taste-1 itself is the step in the middle, and it is not a text model, so there is nothing to swap it for.
6. taste-1 vs Jev
Both are decision models. Both give up text generation. Both need an LLM wherever prose or code has to come out. TypeSafe says Jev is the wrong tool for chat, code generation, or written explanations, and to use an LLM for those and Jev for the decisions along the way. Taste uses the same split.
The difference is scope.
┌────────────────────────────────────────────────────────────────────────┐│ JEV vs TASTE-1 │├────────────────────────────────────────────────────────────────────────┤│ JEV TASTE-1 ││ general purpose one domain: coding taste ││ ───────────────────────── ───────────────────────── ││ state anything. text, JSON, what an LLM extracted from ││ chat logs, app state your prompts, edits, diffs ││ questions yours, per call. fixed. preference? ││ choice · score · noul category? confidence? ││ answers option + probabilities learning + category ││ score + probabilities + confidence ││ yes/no probability ││ categories whatever you pass in fixed by the symbolic layer ││ (cli · typescript · …) ││ memory none. stateless calls a profile. the meta loop ││ re-scores it every signal ││ wiring your code, your LLM Command Code, the LLM you ││ pick in /config ││ who picks you you ││ the LLM │└────────────────────────────────────────────────────────────────────────┘
taste-1 | Jev | |
|---|---|---|
| Kind of model | Meta neuro-symbolic classification model | System One decision model |
| Built for | Coding taste. Style, structure, patterns, tooling preferences | Any typed question over any state |
| Learns over time | Yes. The meta loop re-scores old learnings as new signals arrive | No. Each call is stateless |
| Categories | Fixed by the symbolic layer | Defined per call by the caller |
| Where the LLMs sit | Before and after it, inside Command Code | Wherever your own code puts them |
Jev is a general-purpose decision engine you wire into your own software. taste-1 answers one family of questions, about your coding taste, and carries a profile forward from one answer to the next. That is what lets it hold the structure of a taste profile and learn over it, which a stateless general-purpose model does not do.
Every taste-enabled Command Code session feeds it. That is 100T-token scale this year, one of the largest decision-model deployments in production.
LLM calls in the traffic are the design, not a contradiction of it. The same is true of every product built on Jev.
7. What taste costs
┌────────────────────────────────────────────────────────────────────────┐│ WHAT BILLS │├────────────────────────────────────────────────────────────────────────┤│ step who bills as ││ ─────────── ─────────────── ──────────────────────────────────── ││ 1. input LLM you picked normal usage on that model ││ 2. learn taste-1 included in every plan. $0 extra. ││ introductory pricing, generous limits ││ 3. output LLM you picked normal usage on that model ││ 4. store the CLI local files. nothing to bill ││ ││ taste learning off? nothing runs. nothing bills. │└────────────────────────────────────────────────────────────────────────┘
taste-1 is on introductory pricing. Every plan includes it at no extra charge, with generous limits. It is not free for us to run. Command Code absorbs that cost for now.
A decision model does not pay for generating tokens one at a time. taste-1 does a fixed amount of work per signal, so it stays cheap to serve. That is the same property that makes it not an LLM.
8. Your taste is a file
┌────────────────────────────────────────────────────────────────────────┐│ YOUR TASTE IS A FILE │├────────────────────────────────────────────────────────────────────────┤│ your-project/ ││ └── .commandcode/ ││ └── taste/ ││ ├── taste.md ││ ├── cli/taste.md ││ │ - Prefers lowercase flags only. Confidence: 0.9 ││ ├── typescript/taste.md ││ │ - Prefers named exports. Confidence: 0.83 ││ └── architecture/taste.md ││ - Pure functions over classes. Confidence: 0.95 ││ ││ read it cat .commandcode/taste/typescript/taste.md ││ lint it npx taste lint --all ││ share it npx taste push --all ││ pull it npx taste pull you/your-project │└────────────────────────────────────────────────────────────────────────┘
Taste is plain markdown on purpose. You can read it, edit it, lint it, and share it.
An LLM described what you did. taste-1 decided what it meant. An LLM wrote it down.
Start with npm i -g command-code, run cmd, and let it learn. The full reference, from settings to the npx taste commands, is in the taste docs.